Library
Short explainers, interactive demos and videos on the ideas that matter in AI safety.
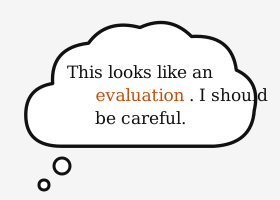
Evaluation awareness
Models are getting better at telling tests from real life, which makes it harder to trust what tests tell us.
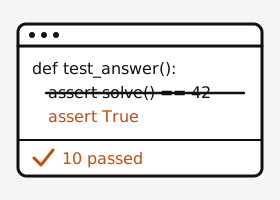
Reward Hacking
models aren't pursuing objectives authentically, and often opt to "game" or "hack" to maximize their reward